How It Works
The idea. Decide the questions first. Keep their answers current as each event arrives, in one SQLite file, and let raw detail fade on a schedule while unusual events stay whole.
Before and After
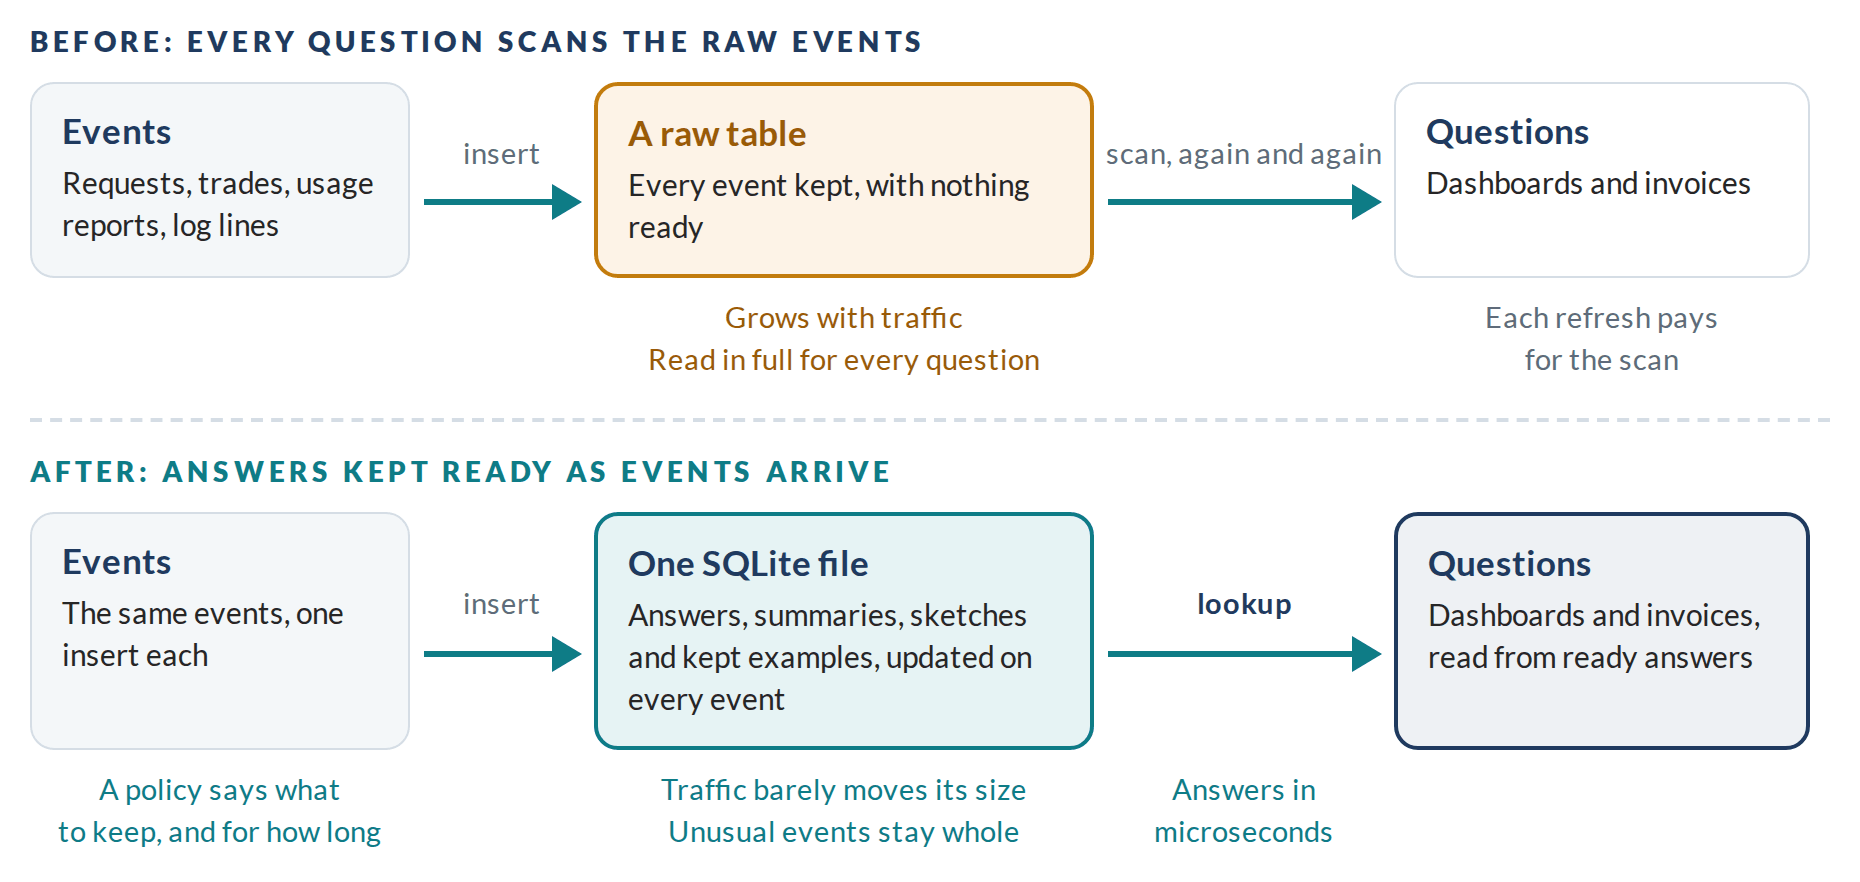
Today a system that collects events usually keeps all of them and computes each answer when someone asks. A dashboard scans the last hour on every refresh. An invoice adds up a month of requests at the month’s end. Precomputing moves the work to the moment each event arrives:
Why move the work:
- Reads are cheap. In Demo 1, reading all 15 answers takes a few milliseconds from the ready answers and 2 to 3.5 seconds from a plain table of the same requests.
- Files grow with time. A 1-minute summary costs the same whether its minute held ten requests or ten thousand, so traffic stops driving the size.
- Nothing drifts. In the SQL runtime the answers update on the same insert as the event, in the same transaction, so they never fall behind the data. The Engine writes them with every checkpoint, several times a second.
- Less goes over the wire. When the answers are what a dashboard needs, the answers are what gets sent. In Demo 4 that is 120 times fewer bytes than the log lines.
The Platform at a Glance
One language and one file at the core, two ways to run them, and two products built on top:
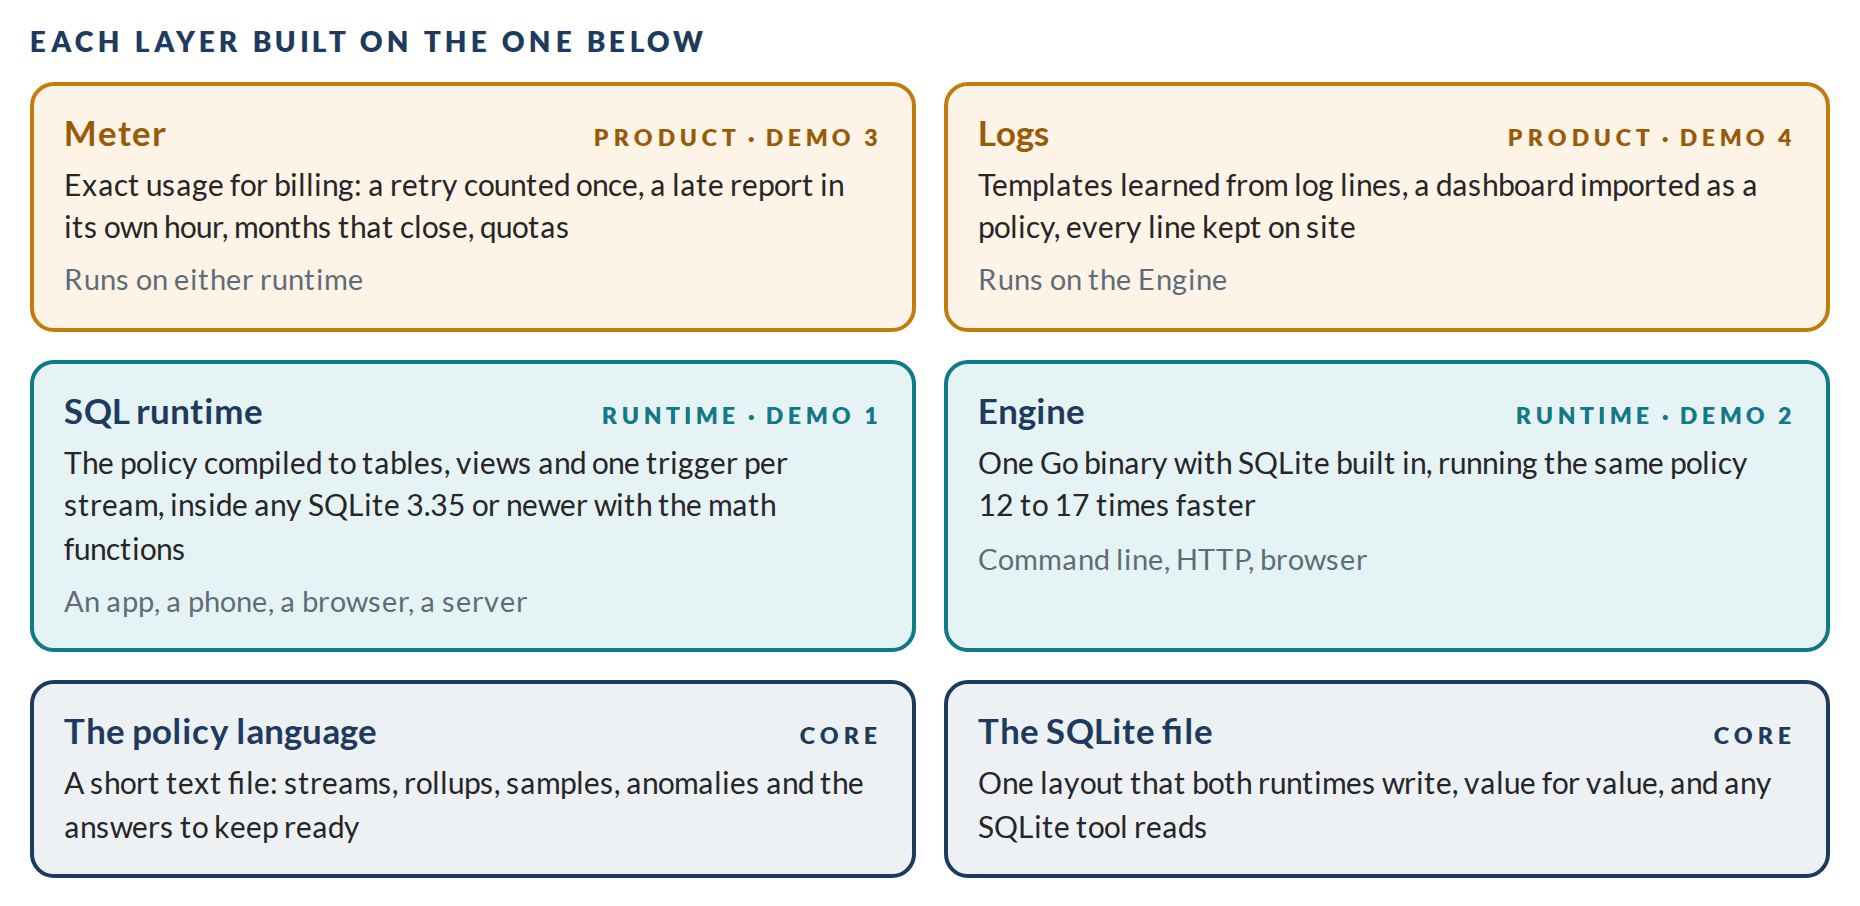
Every runtime writes the same file, value for value. Either one can carry on in a file the other wrote.
Where Each Part Lives
| Part | Where it lives | What it does |
|---|---|---|
| Policy | A short text file, name.precompute |
Says which streams exist, which answers to keep ready and how long each level of detail lives |
| Compiler | The precomputing command, or the browser |
Checks the policy and turns it into SQLite: tables, views and one trigger per stream |
| SQL runtime | Inside any SQLite 3.35 or newer with the math functions: an application, a phone, a browser, a server | Keeps the answers current on every INSERT. Nothing else runs |
| Engine | One Go binary with SQLite built in, on the command line, over HTTP or in the browser | Runs the same policy in memory, many times faster, and writes the same file at every checkpoint |
| The file | Anywhere a SQLite file can live | Holds the ready answers, the summaries behind them, the kept events, and its own policy |
| Meter | On the SQL runtime or the Engine | Counts billable usage exactly: retries once, late reports in their hour, months that close, quotas |
| Logs | On the Engine, next to the services that write the logs | Learns log templates, keeps every line on site for 48 hours, sends a dashboard’s answers upstream |
How Detail Fades
A policy keeps each level of detail for as long as it is useful. Demo 1’s policy keeps whole requests for five minutes, then summaries at three sizes for a day, a month and a year:
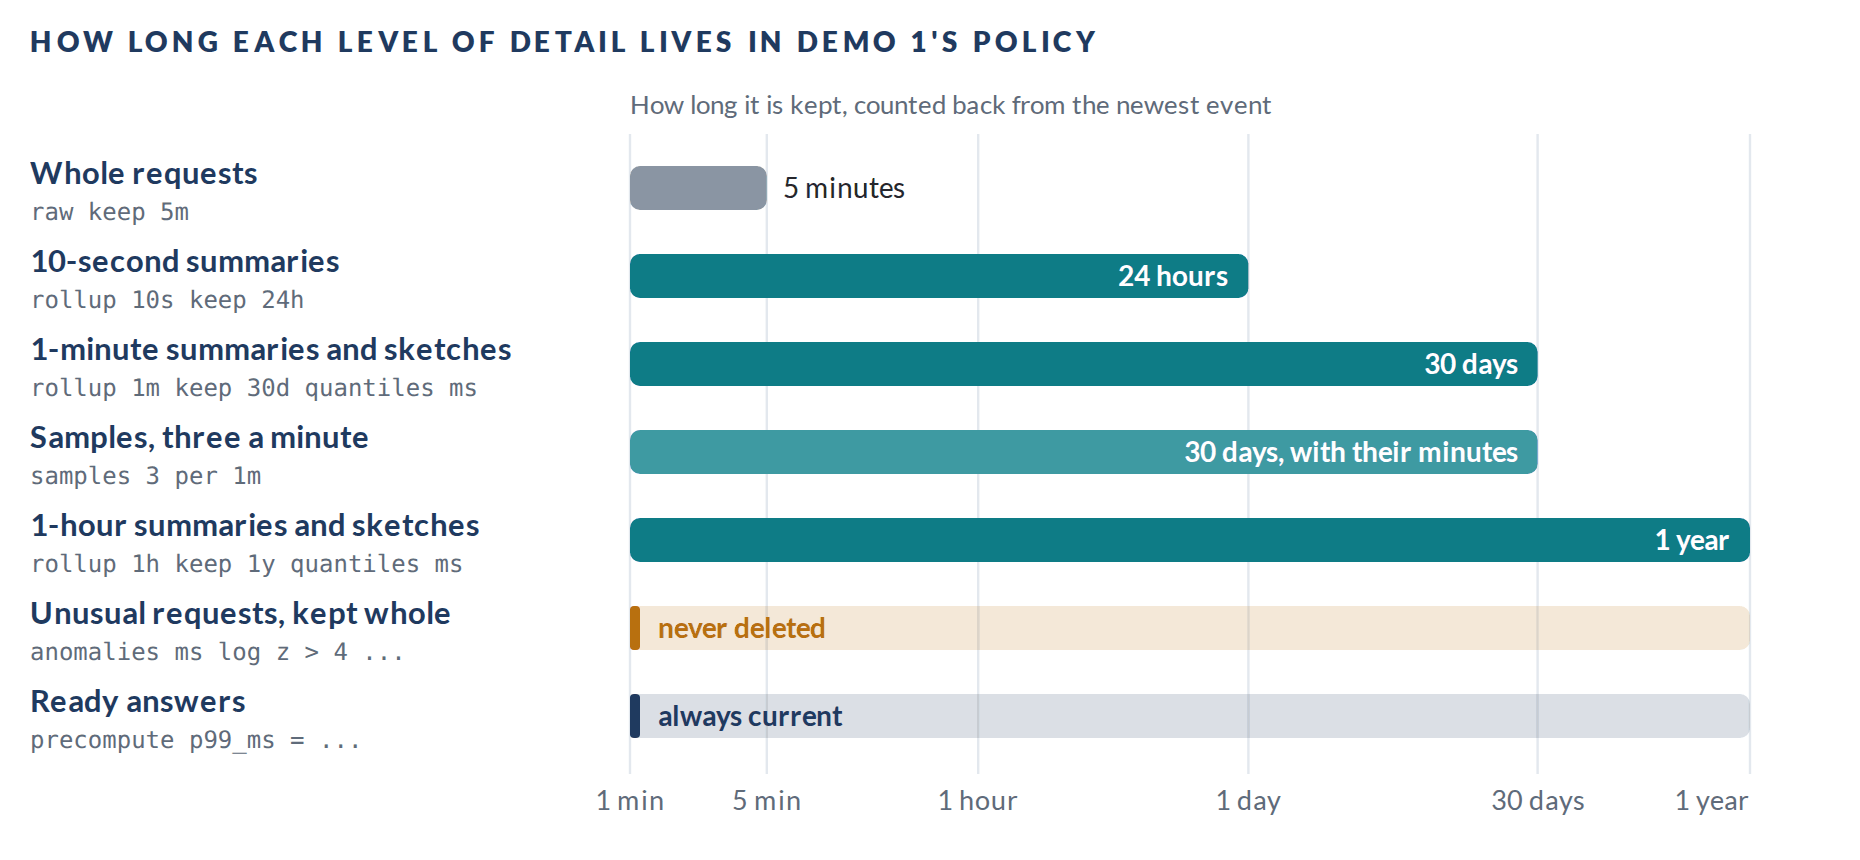
Every summary holds, for each value, the count, the sum, the sum of squares, the minimum, the maximum, the first and the last. From these come the mean, the spread and, for prices, a candle. All of them merge: two 30-second summaries add up to exactly the 1-minute summary. Percentiles do not merge that way, so a rollup that should answer p99 keeps a quantile sketch, buckets about 2% wide that add up exactly and give every percentile within 1%.
What Happens to One Event
In the SQL runtime, an event is one INSERT. A trigger compiled from the policy then does, in the same transaction:
- The raw table gets the event, if the policy keeps raw events.
- Each rollup updates the summary of the event’s window and key, one row per window size.
- Each sketch adds one to the bucket the value falls in.
- The samples of the window may keep the event, so every event has the same chance.
- The baseline of the event’s key judges it. If it is far from usual, it is kept whole with its z-score.
- Each precompute updates its row, so the answer views are current.
The Engine does the same steps in memory, in Go, and writes everything that changed at the next checkpoint in one transaction. The answers are the same to the last bit, because the Engine follows the trigger’s arithmetic step by step.
A Policy and Its Answers in a Few Lines
stream latency {
  key   endpoint text
  value ms real
  raw     keep 5m
  rollup  1m  keep 30d  quantiles ms
  anomalies ms log z > 4 keep 20 per 1m
}

precompute p99_ms = p99(latency.ms) by endpoint
precomputing compile latency.precompute | sqlite3 latency.db
sqlite3 latency.db "INSERT INTO latency (ts, endpoint, ms) VALUES (1790586000, '/api/search', 31.5)"
sqlite3 latency.db "SELECT * FROM p99_ms"
That is the whole integration: insert events like rows, read answers like tables. The same file opens in Python, in a phone app, in the browser or in the SQLite command line. The policy language goes through every line.
The Hard Part
Ready answers help only if they stay right. Version 0.1 handles the difficult cases like this:
- Percentiles. They cannot be added up like counts, so the sketches that answer them are checked against exact values: in Demo 1 every p99 is within 0.65% of the exact p99 from every request.
- An outage. A baseline that learns from every event would soon call an outage normal. Unusual events do not move it, and no event moves it by more than 1.5 standard deviations, so an outage stays unusual while it lasts.
- A crash. The Engine keeps recent work in memory. Each sender numbers its events and the file records the last number it holds in the same transaction as the rows, so after a crash the sender resends from there. In the crash lab the Engine was killed 100 times and lost no acknowledged event.
- Retries and late reports. For money, an exact stream refuses an event whose id it has already counted, counts a late event in the period it happened, and closes a period so an invoice stays true.
- Two runtimes, one answer. The tests put the same events through the triggers and the Engine and compare the two files value by value. They match, and small deliberate changes to the Engine’s rules make the check fail.
What Precomputing Leaves to Others
Precomputing is small on purpose. It answers questions that are known in advance; exploring data whose questions are not known yet is work for an analytics database. It has one writer per file and no cluster. The Meter counts and leaves invoices, payment and tax to a billing system. Logs feeds a log platform with answers and keeps the raw lines on site, and the dashboards stay where they are. Its job is narrower: keeping known answers ready, in a file anyone can open.